ChatGPT Status Report: AI in Genealogy and Family History

The following is ChatGPT’s “Think” (free) response to the same prompt to which Gemini “Search” (free) responded in Status Report: AI in Genealogy and Family History. It’s much longer and references some different (and previously unknown to me) services. Perhaps the “Think” vs “Search” mode has some bearing on its greater breadth and depth. Curiously, the only desktop software it mentions is Family Tree Maker; over a year has passed since I last used ChatGPT to help me with a SQL query of a RootsMagic database.

AI in genealogy and family history: Industry status report

As of November 1, 2026 | Global market overview

Executive summary

Artificial intelligence is becoming a significant part of genealogy and family history software. The industry is moving beyond simple digitization and record matching toward AI-assisted research, document interpretation, family storytelling, and increasingly sophisticated analysis of historical evidence.

The most important development is that AI is beginning to act as a research assistant rather than merely a search engine.

It can help genealogists:

  • Read handwritten historical documents that are difficult to decipher.
  • Extract names, dates, places, and relationships from records.
  • Identify possible matches between people in different records.
  • Suggest new research avenues and explain historical context.
  • Restore, colorize, animate, and interpret family photographs.
  • Generate biographies, narratives, and family history books.
  • Answer questions about a family tree using its underlying data.

However, the industry remains in a transitional phase. AI is much better at helping people find and interpret evidence than at independently establishing genealogical proof.

A major distinction is emerging between established genealogy platforms that are adding AI features and newer AI-native services that are building their products around conversational research.

1. Where AI is being used today

The technology is developing across six major areas.

1. Historical record transcription and indexing

AI handwriting recognition (HTR) and optical character recognition (OCR) convert handwritten and printed records into searchable text. This is one of the most mature and valuable applications because it makes previously inaccessible archives searchable at scale.

2. Record matching and tree expansion

AI helps identify records that may belong to people in a family tree, proposes relationships, and suggests additional ancestors. The technology is moving toward evaluating multiple clues rather than matching names alone.

3. Research assistance and document interpretation

Generative AI can transcribe, translate, summarize, and interpret historical records. It can also suggest where to search next and explain unfamiliar historical terminology.

4. Family photograph enhancement

AI is being used to repair damaged photographs, improve resolution, colorize images, animate faces, and generate descriptions of historical photographs.

5. Biography and family storytelling

AI can turn a collection of dates, records, photographs, and family anecdotes into readable biographies, timelines, narratives, and family history books.

6. DNA and relationship analysis

AI and related computational techniques can help interpret genetic matches, cluster relatives, and investigate possible family connections. This is a more specialized area, and the strongest established methods still rely heavily on statistical genetics and human interpretation.

The first three areas are particularly important for serious genealogical research. The fourth and fifth are especially attractive to consumers who want to preserve and share family memories.

2. Major companies and their AI strategies

The following is a snapshot of the major platforms and emerging services. The distinction is between capabilities that are publicly documented and broader industry direction.

FamilySearch

Research infrastructure

FamilySearch is using AI to make historical records searchable and to help users extend their family trees.

Its AI-enabled capabilities include:

  • Full-Text Search of historical documents.
  • AI-assisted indexing of records.
  • AI Research Assistant with tree-extending hints.
  • Natural-language search and AI help features.

At RootsTech 2026, FamilySearch described a substantial expansion of AI-indexed records. The organization reported growth from 100 million record images in 2024 to 2.3 billion in 2026, with 20 billion more names becoming available through these advances. FamilySearch+1

MyHeritage

Consumer AI experience

MyHeritage has one of the broadest consumer-facing AI feature sets in genealogy.

Its products include:

  • Deep Nostalgia for animating historical photographs.
  • Photo enhancement and colorization.
  • AI Record Finder.
  • Scribe AI for document and photo analysis.
  • AI Biographer for automatically generating ancestor biographies.

Scribe AI, introduced in March 2026, can transcribe and translate documents, extract genealogical details, and analyze photographs for clues about when and where they were taken. AI Biographer, introduced in July 2026, generates biographies from family tree profiles and matching historical records. MyHeritage Blog+1

Ancestry

Records and discovery

Ancestry’s core strategic advantage is its large historical record collection, extensive family trees, and DNA database.

AI is being applied to:

  • Handwriting recognition.
  • Record matching and family tree hints.
  • Extracting information from historical documents.
  • Generating summaries and descriptions of family history materials.

Ancestry’s opportunity is to combine AI with its extensive proprietary data, rather than compete solely on the underlying AI model. The company’s AI-related developments were also discussed at RootsTech 2026. Church News

Goldie May

AI research workflow

Goldie May is focused on assisting genealogists with the research process itself.

Its AI assistant can help researchers increase their research output, explore evidence, and identify useful next steps.

This is an important direction because professional genealogists often spend more time managing research and evaluating evidence than simply locating names. Goldie May’s AI research capabilities were highlighted at RootsTech 2026. Church News

AncestralFire

AI-native research

AncestralFire is an example of a newer service built around conversational family history research.

It connects AI assistants with a user’s family tree and research sources. Its approach emphasizes evidence-based answers, citations, and user approval before changes are made to a tree. AncestralFire

Heartwood

Local-first AI

Heartwood represents another emerging model: genealogy software that works with the user’s preferred AI assistant.

It emphasizes locally stored research data, evidence-linked claims, and a workflow in which AI suggestions remain unconfirmed until the researcher accepts them. Heartwood

The industry is therefore developing along two different paths:

  • Large genealogy platforms: AI is integrated into proprietary records, matching systems, and consumer experiences.
  • AI-native platforms: AI is the primary interface for interacting with family trees, records, and research workflows.

The second category is particularly interesting because it could change the way people interact with genealogy software altogether.

3. Technology maturity: what works and what doesn’t

A useful way to assess the industry is to separate the maturity of the underlying AI technology from its reliability as a genealogical research tool.

ApplicationMaturityPractical assessment
Printed record OCRHighVery useful for searchable archives
Handwriting transcriptionHigh, but variableStrong on legible documents; less reliable on difficult scripts
Record extractionHighGood at extracting names, dates, places, and occupations
Record matchingHighUseful for generating candidate matches
Document translationHighValuable for multilingual research
AI photo restorationHighUseful, but can alter historical details
Photo dating and interpretationMediumUseful for generating clues, not definitive dating
Family biographiesMedium-highGood at writing; dependent on source quality
Conversational research assistantMedium-highIncreasingly useful when connected to real sources
Autonomous genealogical proofLowNot reliable enough to establish relationships independently
DNA-based relationship inferenceMedium-highStrong in established statistical methods; AI is supplementary

These are qualitative assessments of practical utility, not standardized benchmark scores.

The central technical limitation

AI can produce a plausible explanation for a family relationship even when the evidence is insufficient.

For example, it may identify two people with the same name, living in the same county, and suggest they are father and son. That may be a useful lead, but it is not proof.

The more consequential the relationship, the more important it becomes to distinguish:

  • A confirmed fact.
  • A record-supported inference.
  • A possible relationship.
  • An AI-generated hypothesis.

This distinction is essential if AI-generated information is going to be incorporated into a permanent family tree.

FamilySearch itself emphasizes the need to review AI results and verify information before incorporating it into genealogical research. FamilySearch+1

4. The emerging competitive landscape

The most significant strategic question is: Who will own the AI interface to a person’s family history?

Historically, genealogy software has been organized around:

  • Family tree diagrams.
  • Individual person profiles.
  • Historical record search.
  • Source citations.
  • Data entry and relationship management.

AI creates the possibility of a different interface.

A user could ask:

Why did my great-grandfather leave Ireland in 1882?

The system could potentially:

  1. Examine the ancestor’s existing records.
  2. Identify the relevant locations and dates.
  3. Search immigration, census, newspaper, and land records.
  4. Compare the available evidence.
  5. Explain the historical context.
  6. Identify gaps in the research.
  7. Suggest the next records to investigate.
  8. Generate a documented narrative of the findings.

That is a much more compelling experience than asking a user to search through dozens of databases independently.

The challenge is that this experience requires more than a language model. It requires access to historical records, structured family tree data, reliable source retrieval, and a system for tracking evidence.

Three emerging business models

MODEL 1

AI-enhanced genealogy subscriptions

Established companies add AI features to existing subscription products. AI helps improve retention, increase engagement, and justify premium pricing.

Examples: Ancestry and MyHeritage.

MODEL 2

AI genealogy research assistants

The product is centered on asking questions, analyzing evidence, and guiding the research process.

Examples: Goldie May and AncestralFire.

MODEL 3

AI-powered family history creation

The product turns existing research and family materials into biographies, books, timelines, and multimedia stories.

This model can serve a much broader market than traditional genealogy enthusiasts.

The third model is especially interesting from a commercial perspective. Many people are interested in preserving family memories but are not interested in conducting genealogical research themselves.

5. Major opportunities for further development

Several areas appear particularly promising.

A. Evidence-aware AI

The next generation of genealogy software should distinguish between facts and hypotheses.

A strong system would:

  • Attach every factual claim to a source.
  • Show conflicting evidence.
  • Explain why a relationship is suggested.
  • Maintain confidence levels.
  • Avoid automatically incorporating unsupported claims.

AncestralFire and Heartwood illustrate the emerging emphasis on evidence-linked AI and human review. AncestralFire+1

B. Cross-platform family history intelligence

Most family historians have information spread across multiple systems:

  • Ancestry.
  • FamilySearch.
  • MyHeritage.
  • Family Tree Maker.
  • Legacy Family Tree.
  • Local GEDCOM files.
  • Personal document collections.

An AI system that can analyze a person’s entire research collection, rather than just one platform, could offer substantial value.

The challenge is interoperability, data quality, and access to proprietary records.

C. AI for professional genealogists

Professional researchers could benefit from AI that helps with:

  • Research planning.
  • Record transcription.
  • Source extraction.
  • Citation creation.
  • Evidence comparison.
  • Client reports.
  • Research logs.
  • Identification of unresolved questions.

The opportunity is not necessarily to replace the genealogist. It is to reduce repetitive work and allow more time for difficult research problems.

D. Family history storytelling

AI can transform genealogical research into products that family members actually want to consume.

Potential outputs include:

  • A biography of an ancestor.
  • A family history book.
  • A narrated family tree.
  • A historical timeline.
  • A collection of family stories.
  • A digital family archive.
  • A personalized family history website.

MyHeritage’s AI Biographer is an example of this direction. It uses family tree information and historical records to create biographies of deceased relatives. MyHeritage

E. Genealogy as a conversational experience

A particularly promising direction is the ability to interact with a family tree through natural language.

Instead of navigating through profiles, a user could ask:

  • “Show me all the ancestors who immigrated to Canada.”
  • “Which branches of my family came from Scotland?”
  • “What do we know about my grandmother’s childhood?”
  • “Which relationships in my tree are still uncertain?”
  • “What records should I search next?”

This could make genealogy accessible to people who find traditional family tree software complicated.

6. Risks and unresolved issues

The technology has significant potential, but the following issues need to be addressed.

Hallucinated family relationships

AI may invent details or infer relationships without sufficient evidence. This is the most important research-quality risk.

Historical record errors

AI can faithfully extract incorrect information from a record. A transcription error can propagate through multiple generations.

Privacy and living people

Family trees often contain information about living relatives. AI services must handle sensitive information carefully, particularly when users upload records or connect external accounts.

Synthetic photographs

AI restoration and colorization can create details that were never present in the original image. Users should be able to distinguish enhanced images from historical originals.

Copyright and access to records

Historical records, digitized newspapers, and photographs may have licensing or usage restrictions. AI does not eliminate those restrictions.

Vendor dependence

Users may become dependent on a particular platform’s AI tools, proprietary records, and data formats. Exportability and interoperability remain important.

7. Overall assessment

My assessment is that AI in genealogy is transitioning from an experimental feature set to a core product capability.

The strongest developments are occurring in three areas:

  1. Making historical records searchable. AI is unlocking enormous quantities of previously inaccessible information.
  2. Helping researchers interpret evidence. AI is becoming a useful assistant for transcription, translation, research planning, and record analysis.
  3. Making family history more engaging. AI is helping transform family tree data into stories, biographies, and visual experiences.

The next major leap will likely come from systems that can combine these capabilities into a coherent research workflow.

The winning product will not necessarily have the most sophisticated AI model. It will be the one that combines reliable data, excellent research tools, transparent evidence, and an intuitive experience.
Selected sources

RootsMagic & AI Genealogy Comparative Analysis

This too is a Gemini response to the prompt “How does RootsMagic Family Tree software fit into AI assisted Genealogy and history research, analysis and reporting? How does it compare in this regard with other family tree software and services?” I had it replace its first single comparison table with two to accommodate more software and services.


RootsMagic occupies a distinct niche in AI-assisted genealogy. While web-first mega-platforms emphasize proprietary, automated AI black-boxes (such as automated photo colorization or closed matching algorithms), RootsMagic focuses on structured data export, local database control, and flexible prompt-building for third-party Large Language Models (LLMs).

Instead of building a locked-in, native generative AI directly into its desktop code, RootsMagic operates as an unstructured-to-structured data pipeline.

How RootsMagic Fits into AI-Assisted Genealogy

RootsMagic serves as a reliable human-in-the-loop anchor for AI workflows.

1. Native AI Prompt Builder (RootsMagic 12+)

RootsMagic features an integrated AI Prompt Builder. Rather than sending your private database automatically to an external server, it extracts context-specific data points from your local database—bound by person, family, source, or place—and constructs structured, token-optimized prompts.

  • Person/Family Context: Constructs targeted prompts to generate draft biographical narratives, timeline summaries, or research logs by injecting clean factual nodes (birth, marriage, census events, place hierarchies) into your preferred AI model, such as ChatGPT, Claude, or Gemini.
  • Source & Place Context: Prepares source citation strings or geographic metadata to prompt LLMs for historical background, record loss risks (e.g., burned county court records), or local administrative changes.

2. SQL Control for AI-Powered Data Extraction

RootsMagic stores its underlying data in an accessible SQLite format. Advanced researchers frequently bypass standard export interfaces to run custom SQLite queries.

  • Cleaning AI Extractions: When using vision-language models or OCR/HTR pipelines—such as Transkribus—to parse old wills or land deeds, the resulting structured data (e.g., CSV or JSON tables of dates, names, and witness roles) can be validated and batch-inserted back into RootsMagic database tables.
  • Data Hygiene & Anomaly Detection: AI tools can analyze exported SQLite database tables (such as the PersonTable or EventTable) using custom scripts to identify impossible timelines, missing child-parent relationships, or place-name inconsistencies.

3. Synthesizing Evidence vs. Source Citations

RootsMagic maintains a strict separation between source citations and raw transcribed text. Because AI requires evidence (the actual contents of a document) rather than just a citation (where to find it), RootsMagic allows you to feed full transcriptions stored in research notes or source text fields directly into AI prompts. This enables LLMs to evaluate conflicting evidence or analyze complex relationships across census years.

Major Online Platforms & Services

Online platforms leverage massive cloud compute to run background indexing, handwriting recognition (HTR), and record-matching models across billions of historical documents.

PlatformCore AI Architecture & FocusKey AI FeaturesPrimary Limitation / Risk
FamilySearchLarge-Scale HTR & Full-Text Search
Scans raw document images using vision-language models.
• Full-Text Search: Scans un-indexed record images (deeds, probate, church registers) to search whole body text directly.
• Automated indexing pipelines for community review.
High volume of transcript variations on older/damaged handwriting; requires human audit against original images.
Ancestry.comProprietary Record Matching & Search Indexing
Trained on billions of linked records and trees.
• SideView™: Uses machine learning to phase DNA matches by parental side without requiring parent testing.
• Automated HTR across historical land and census records.
Matching algorithms occasionally propagate unverified user-tree errors across hints.
MyHeritageDeep Learning & Photo/Media Synthesis
Consumer-facing computer vision and photo enhancement tools.
• DeepStory: Generates video/audio avatars from photo portraits.
• Photo Enhancer: Automatic scratch removal, upscaling, and colorization.
• Record Detective 2: Cross-links records via contextual AI.
High potential to create unauthentic historical artifacts; deepfakes/reconstructions can be mistaken for historical reality.
FindmypastNewspaper Extraction & Context Matching
Focuses on UK/Irish press and parish records.
• Smart Press Indexing: Applies AI transcription to degraded, multi-column 18th- and 19th-century newspapers.
• Contextual record-hinting engine across military and parish registers.
OCR/HTR struggles with dirty newsprint, leads to missed surname hits in press archives.

Desktop & Personal Family Tree Software

Desktop programs emphasize data privacy, local database governance, and bringing AI into structured software workflows.

SoftwareCore AI Architecture & IntegrationKey AI FeaturesPrimary Limitation / Risk
RootsMagicStaging & Prompt Engineering
Extracts structured context to build targeted prompts for external LLMs.
• AI Prompt Builder: Converts local person, family, and source nodes into token-optimized prompts for ChatGPT/Claude.
• Direct SQLite interface for AI-assisted data cleaning and anomaly detection.
No native offline LLM engine built into the UI; requires copying/pasting or running scripts to external models.
Family Historian 8AI Connector & Plugin API
Connects directly to LLMs (Claude/OpenAI) with read/write database permissions.
• AI Connector: Natural language querying (“List men of conscription age in WWI”).
• Automated document reading, citation creation, and inconsistency checking directly inside the project file.
Requires a separate LLM API account/subscription; write-permission requires user supervision to prevent database corruption.
Heredis 2027In-App AI Reading Assistant
Embedded European-hosted AI pipeline focused on document extraction and translation.
• Reading Assistant: Automatically transcribes and translates records (Latin, German Kurrent, French, Spanish).
• Tree Builder: Auto-extracts names, dates, and relationships from scanned documents to create tree nodes.
Dependent on Heredis cloud processing servers for transcription tasks.
GrampsOpen Source Python Ecosystem
Community-driven scripts and API integrations.
• Custom Python Plugins: Community scripts for linking external OCR/HTR workflows.
• Export scripts designed to feed graph databases or local LLMs (like Ollama).
Requires technical expertise; no turnkey “one-click” AI features out of the box.
Family Tree Maker (FTM)Sync & Mirroring Pipeline
Focuses on syncing indexed data from online partners.
• Relies on Ancestry and FamilySearch backend AI for hint generation and sync.
• No standalone or native LLM/HTR tools built directly into the desktop client.
Limited to the AI capabilities of its sync partners; no direct local AI prompt or extraction workflows.

Key Takeaways

  1. RootsMagic is an Orchestrator, Not a Black Box: Unlike MyHeritage, which builds consumer-facing “fun” AI features (animating photos, auto-generating video biographies), RootsMagic focuses on assisting serious researchers in preparing accurate data for custom analytical prompts.
  2. Data Governance over Automation: Web-first platforms use AI to drive discovery across billions of cloud records. RootsMagic keeps your master data local, protecting user privacy and avoiding automatic, unverified AI changes to your main tree.
  3. The Best of Both Worlds: The most common professional workflow pairs web platforms (using Ancestry/FamilySearch AI to discover and transcribe records) with RootsMagic as the desktop repository. Here, LLMs can be queried on-demand to write narratives, translate records, or spot research gaps without corrupting the underlying database. (The Best Genealogy Software (2026): Free, Paid, and AI Compared, RootsMagic 12’s AI Prompt Builder – Have You Tried It?)

Status Report: AI in Genealogy and Family History

The following report was generated by Gemini in response to the prompt:
Give me a status report on the use of AI in human family tree and family history software and services.
The conversation went on and I will post some follow-up that could be of interest to RootsMagic users.


The integration of artificial intelligence into genealogy has moved beyond gimmickry into practical core infrastructure. AI tools are actively streamlining archival processing, record extraction, and data organization, while generative text models provide historical context.

At the same time, the fundamental rule of genealogy remains unchanged: AI accelerates hypothesis generation, but human verification against primary sources remains essential.


Core Areas of AI Implementation

1. Handwriting Recognition & Automated Indexing (HTR)

Handwritten Text Recognition (HTR) is arguably the most impactful application of AI in genealogy today.

  • FamilySearch & Public Archives: Large-scale automated indexing projects use vision-language models to process un-indexed or image-only historical record collections (such as parish registers and probate records). Records that previously took volunteers decades to index are now text-searchable through tools like FamilySearch Full-Text Search in a fraction of the time.
  • Transkribus & Custom Models: Specialized platforms like Transkribus allow researchers to upload difficult historical hands—ranging from 18th-century cursive to German Kurrent, Latin, or Cyrillic—to produce automated transcripts with high accuracy.

2. Specialized Search & Record Matching

Commercial repositories are leaning into AI to move beyond exact-match string searches:

  • Ancestry & MyHeritage: AI-driven matching algorithms analyze tree structures alongside record collections, looking at contextual hints (e.g., matching occupation, nearby land boundaries, or common naming patterns) rather than relying solely on name/date hits. For example, Ancestry utilizes machine learning for tools like SideView™ to phase DNA matches by parental side.
  • Findmypast: Implements AI-powered transcription across historical newspaper collections, making surname and location searches practical across vast press archives via Findmypast.

3. Photo Enhancement & Computer Vision

Visual AI remains a high-visibility feature, though opinions in the genealogy community are split between utility and historical preservation.

  • Restoration & Upscaling: Deep-learning models effectively remove scratches, sharpen focus, and correct color fading, as seen in the MyHeritage Photo Enhancer.
  • Facial Recognition: Tools automatically tag potential matches of unknown relatives across photo albums by matching facial structures across different ages.
  • Generative Manipulation: Features like portrait animation (MyHeritage DeepStory) or cross-generational composite family photos are popular for engagement, though seasoned researchers caution against confusing creative reconstruction with historical evidence.

4. Document Structuring & Local Research Assistants

A growing shift in desktop and web tools focuses on turning unstructured documents into structured relational data.

  • Emerging platforms and custom LLM workflows allow researchers to upload scans of wills, deeds, or letters. The AI extracts structured facts (names, roles, dates, relationships, locations) and auto-links them to existing tree nodes or databases.
  • Genealogists routinely use general LLMs—such as ChatGPT, Claude, or local open-weights models running via Ollama—to interpret archaic terminology, translate Latin vital records, or construct historical context summaries.

Current Industry Challenges & Limitations

  • Hallucinations in Tree Building: Generative AI models struggle with strict evidence evaluation. When asked to “fill in a family tree,” models frequently invent missing ancestors, mix up individuals with identical names, or synthesize plausible-sounding but nonexistent sources.
  • Privacy & Opt-In Concerns: Platform integrations of third-party AI features have sparked community debate regarding data sharing, auto-opt-in defaults for user trees, and copyright over user-contributed records.
  • Citation & Provenance: Automatically extracted metadata still requires human audit. AI tools frequently miss subtle transcript cues (e.g., ditto marks, marginal notes, or crossed-out entries) that dramatically alter record interpretation.

Summary Matrix

Feature / TaskAI MaturityBest Used ForPrimary Risk / Limitation
Cursive & Manuscript HTRHighUn-indexed parish records, wills, journalsMisinterpreting regional abbreviations or phonetic spellings
Translation & Record ReadingHighLatin, German, Scandinavian vital recordsSubtle legal terminology mistranslations
Photo RestorationHighSharpening, scratch removal, color recoveryFabricating details in severely degraded faces
Record Matching / HintsMedium-HighSurfacing leads across massive datasetsPropagating unsourced or wrong tree connections
Automated Tree ConstructionLowDraft generation, timeline brainstormingHallucinating individuals, conflating same-name people

RM11 Bug – Duplicate Couples from FamilySearch Download – Workarounds

UPDATES

  • 2026-08-26: added Purple to colorcoding to highlight significant children; replaced image zoom on click to open in browser.
  • 2028-08-27: replaced two queries that proved to be unusably slow on larger databases with far faster ones.

Problem

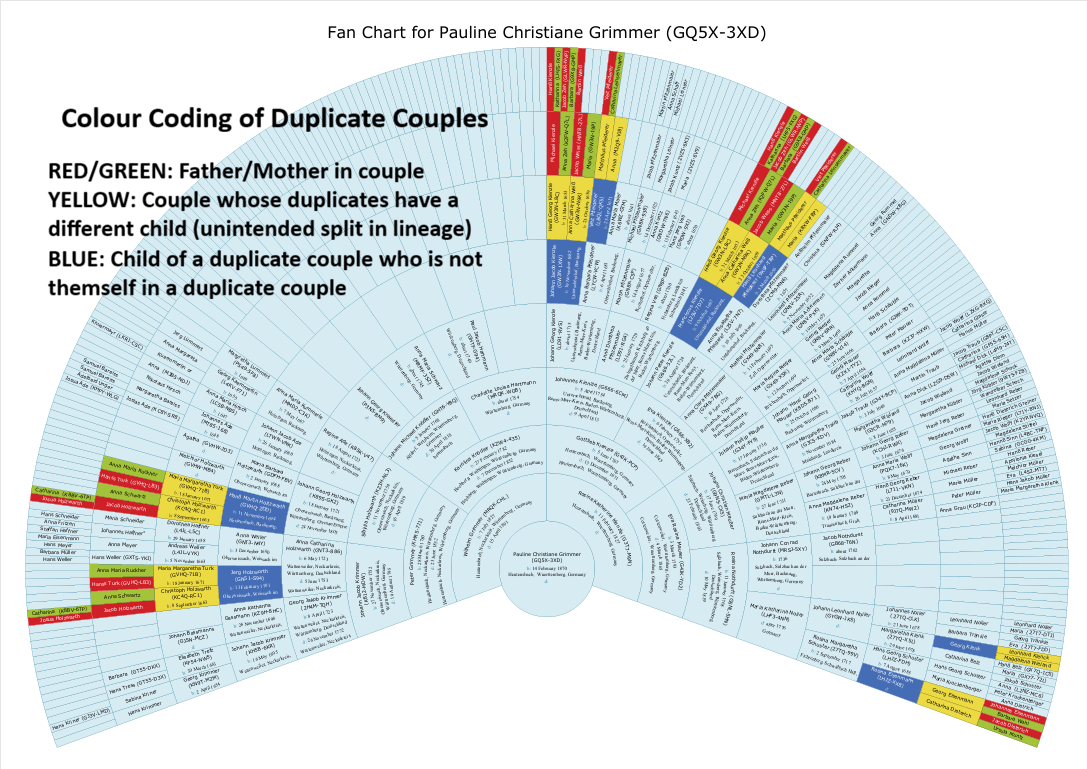
Custom colour coding using SQLite to pop out the areas of erroneous duplication of lineage on this Fan chart by RootsMagic 11.5 for Pauline Christiane Grimmer (GQ5X-3XD) in a database created by a download of ancestors of Helmut Karle Heinle (P6Y1-S8M) from FamilySearch Family Tree on 2026-08-14. A later download may have different results because FSFT is in a constant state of flux from multiple editors adjusting it to show what each wants or believes or has proven to be true. However, the duplication of lineage that shows up in the RM download is evident neither on the FSFT website nor in a similar download using Ancestral Quest Basic.

If ancestral lines join below their most-recent-common-ancestor in a tree branch downloaded from FamilySearch, RootsMagic 11.5 duplicates the common lineage. Duplicate couples are created, one of which has a child that the other does not and vice-versa, just above the junction. This results in an overstatement of the numbers of families, spouses and children in various outputs, miscalculation of relationships and probable graphic errors. Moreover, transfer of certain sets of members from a database so corrupted can propagate it via GEDCOM or drag’n’drop to others. There is some evidence to suggest that it has been an issue starting with RM8; regardless, it is popular to download large segments of the FSFT so it is likely there are many RootsMagic user databases afflicted with it.

RootsMagic Inc. is aware of the issue; it came to a head in this discussion in the Community Forum, Double parents after import via FSID, started by Thomas Burkhart, 2026-08-14, in which he describes the scale of manual edits needed to correct the mistakes. What is needed at this juncture:

  1. Tools to help find where such problems lie in the database. These will aid analysis of why it’s happening and editing to correct defects in the data.
  2. Tools to batch find and correct the defective data.
  3. Alternative procedures to get the data into a RM database

That’s the order in which I tackled them but the general user is likely interested in the reverse.

Alternative Import from FSFT

Download and install the free Ancestral Quest Basic from Incline Software. Descended from the pioneering software Personal Ancestry File, it has a FamilySearch download feature that is similar to that of RootsMagic and maybe faster. You can choose either ancestors or descendants of the starting person, not both as you can with RM. On completion of the creation of the new database in AQ, export it to a GEDCOM file, choosing the “Other” option.

With RootsMagic, import the .GED file from AQ into a new RM database. In my test, the LST file of the same name as the database reported no import difficulties. In FamilySearch Central, you will see that everyone is matched with FamilySearch and RM will be busily finding that FSFT has new information for everyone. That’s unfortunate because there would likely have been little change between the download and the starting up of FS Central in RM. However, I think that may be consistent with the way RM functions if it had downloaded directly. There must be information additional to what comes through the download itself that FS Central wants. Warning: the filter “People not matched to FamilySearch” ties up the RM user interface for a long time until it displays nobody yet the opposite filter is very fast at displaying everybody.

I am not a fan of the FamilySearch Family Tree and rarely use RootsMagic’s FamilySearch Central. Hopefully, I’ve not missed a ‘gotcha’ on this workaround.

Batch Find and Correct the Defective Data

There are a couple of these solutions in progress that will be of interest to some so inclined. One by @richardotter and the other by me. Richard is the pro programmer of the two.

Python script by Richard Otter with CoPilot

Richard posted a preview link in this comment in the discussion “Comments on the Gemini Script for Deduplication of Children” in a forum on this site. It sounds like it could be a solution not only for fresh downloads from FamilySearch but also for older databases that have this lineage corruption when there are attachments such as Citations, Media, WebTags added to family-type events (Marriage, Divorce,…) for the secondary couple(s) in a duplicate set. Because the secondary couples will be deleted, anything uniquely tagged to them and not the primary couple needs to be transferred. His solution does that.

SQLite script by Tom Holden with Gemini

So far, my approach has been on fresh downloads as I have spent much time examining them to gain some understanding of what is going on. Because there are no Citations, Media et al in a download from FS, I’ve not addressed their preservation in this SQLite script. It is a distillation of several queries developed for analysis of the data into one batch streamlined for speed. These four steps are done in sequence within one transaction:

  1. Re-link children attached to duplicate families to the primary FamilyID
    Deduplicate identical child links pointing to the same primary FamilyID
  2. Re-link unique family events from duplicate families to the primary FamilyID
  3. Delete duplicate couple records from FamilyTable
  4. Clean up orphaned family events

DuplicateCouples-CLEAN_DELETE.sql << click to view, copy, download

Finding the Problems

Graphics

Colour Coding

Rev 2026-08-26 with PURPLE to denote children of duplicate parents that are not common to the children of the other duplicate parents. Thought to be significant markers of the vicinity where RM makes an error.

Use it before cleaning if you wish to explore where there are duplicates in the displays and charts available in RootsMagic, such as the fan chart at the top of the page. This coding pattern is most useful with the fan chart, starting at the root of the tree and out to as many ancestor generations imported or about 16, whichever is less. Beyond that, I find RM gets very slow generating a chart at that scope or can even freeze, on a gaming-capable laptop in the low end of the mid-range (Intel Core i9, nVidia GEFORCE RTX 5060 GPU, which probably does not get called upon). If the color patterns are far out and there is no text, traverse the radius out toward one as far as the last person in common with its near-duplicate pattern (same members but one). Choose that person and generate the chart anew so you can see the names, FamilySearchID or RIN in the boxes.

18-generation fan chart colour-coded for duplicate couples problem
18-generation fan chart colour-coded for duplicate couples problem.

Lists

Duplicate Couples (updated 2026-08-27)

Lists duplicate couples. Temporary VIEW created to conveniently review results without reopening the SQL file. Updated 2026-08-27 for vastly improved performance on larger databases.

FatherIDFatherFSIDFatherNameMotherIDMotherFSIDMotherNameDuplicateCountDuplicateFamilyIDs
1360KHDL-X5ZDieterich, Jacob1363K4JM-B9YMuntz, Ursula2496, 582

Children of Duplicate Couples (updated 2026-08-27)

Lists children of duplicate couples. Temporary VIEW created to conveniently review results without reopening the SQL file. Updated 2026-08-27 for vastly improved performance on larger databases.

ChildIDChildNameFatherIDMotherIDCoupleFamilyIDs
921Dieterich, Catharina13601363496, 582

Both of the above create temporary stored queries (a VIEW) that can be selected from the SQLite manager’s database objects to view its results, just as you would to view a table. The application issues a simple SELECT to fetch everything from the VIEW. After running the CLEAN_DELETE script, both of these VIEWs should be empty.

Uncommon Children of Duplicate Parents

Added 2026-08-26: lists a subset of the children of duplicate couples – those that are not common to all the other children linked to the other duplicate parents. The colorcoding script applies Purple to these people as they are thought to be significant markers of the vicinity where RM makes an error and generates a duplicate couple.

As published the script simply lists ChildID, FatherID, MotherID (ID=RIN) but there is a commented out section for a query that will also fetch the FamilySearch ID and Names of the people. You can selectively execute it or uncomment it to be executed with the core script.

Delete Duplicate Child-Parent(s) Relationships

UPDATE 2026-08-17 This page is NOT applicable to the case described in the Community Forum. Having imported the problem tree branch reported there, I’ve found that the duplication of ChildParent linkages is due to there being duplicate Couples (two FamilyIDs) to which the Child is separately linked. So the queries below fail to address the actual cause of the problem. More coming in a later post.

A user reported that having imported the ancestors of a certain person from FamilySearch through RootsMagic 11 that a large number of children ended up showing duplicate parents in RM but not on FamilySearch. He sought a way to eliminate them, other than by finding and fixing every instance, one-at-a-time, through RootsMagic. (see Community Forum)

Gemini Flash (fast) generated the following queries with very little direction from me. They should be compatible with all versions from RM4 to RM11.

Identify

The first and more complex one identifies the duplicates, as in this example using SQLiteSpy:

SELECT 
    c.ChildID,
    cn.Given AS Child_Given,
    cn.Surname AS Child_Surname,
    f.FamilyID,
    fn.Given AS Father_Given,
    fn.Surname AS Father_Surname,
    mn.Given AS Mother_Given,
    mn.Surname AS Mother_Surname,
    COUNT(*) AS Duplicate_Count,
    GROUP_CONCAT(c.RecID) AS ChildTable_RecIDs
FROM ChildTable c
-- Join primary name for the child
LEFT JOIN NameTable cn 
    ON cn.OwnerID = c.ChildID 
   AND cn.IsPrimary = 1
-- Join family record
JOIN FamilyTable f 
    ON c.FamilyID = f.FamilyID
-- Join primary name for the father
LEFT JOIN NameTable fn 
    ON fn.OwnerID = f.FatherID 
   AND fn.IsPrimary = 1
-- Join primary name for the mother
LEFT JOIN NameTable mn 
    ON mn.OwnerID = f.MotherID 
   AND mn.IsPrimary = 1
GROUP BY c.ChildID, c.FamilyID
HAVING COUNT(*) > 1;

The above script is not needed to clean out the duplicates but may be of value in analysing how they came about before deletion.

Delete

This second query is the tool for bulk deletion of the duplicates and is short and sweet:

DELETE FROM ChildTable
WHERE RecID NOT IN (
    SELECT MIN(RecID)
    FROM ChildTable
    GROUP BY ChildID, FamilyID
);

Prompting Gemini

In the previous couple of years, I gave AI very detailed directions including the key data definitions I knew it would need. This year, I have found that they have learned a lot about RootsMagic databases and need less direction in the user prompts. Gemini got the second query right on its first attempt but needed correction for the first query. Below are the two prompts I gave it:

A RootsMagic database has unwanted duplicate child-parents relationships. Generate a SQLite query that identifies the children and the parents. Then generate a second query that deletes the duplicates. Do you need me to tell you the objects in the database that need to be involved in these queries? 

It said it had all the information it needed but proceeded on the wrong assumption of where the names of the child and parents are stored, so…

Your first query fails because it mistakenly assumes that the person’s names are found in the PersonTable. Instead they are found in the FamilyTable. While the PersonTable generates the PersonID key which relates to other tables, its information about the person is limited to Sex and a Note. The rest of it is primarily registers in support of the user interface. Do you need direction on retrieving the primary name values from NameTable?

That corrected the Identify query and Gemini asked, “Would you like a query to check for orphan records or integrity issues after running the delete?”

Yes, I am curious to see what orphans and integrity issues you would check for and how you would do it.

It responded with several which I will simply list because I’ve not tested them:

  1. Database Engine Health Checks
  2. Orphaned ChildTable Records (Dangling Links)
  3. Orphaned Parent References in FamilyTable
  4. “Ghost” Families (Empty Family Containers)
  5. Logical Anomaly: Child as Their Own Parent

It then asked “Want me to generate automated DELETE queries for any ghost families or orphaned child records found by these checks?” Yes and then it produced three plus a consolidation of the three, all untested:

  1. Delete Orphaned ChildTable Records
  2. Delete “Ghost” Families
  3. Repair Invalid Parent References in FamilyTable
  4. Complete Safe Execution Script

CSV: Reverse order, comma count queries #places #AI

Two SQLite queries developed by DeepSeek under my direction:

  • Update the Reverse column in PlaceTable from the Name, a comma-separated string
  • Count the number of commas in Place Name for each Place

These queries can be adapted to other SQLite database columns that employ comma-separated strings.

Problem

These queries were created when I was asked to convert Place Details into Places in a very large database with 48,000 records in the PlaceTable. I was able to use my old scripts from Places – Conversion of Place Details to Places to do the conversion but RM9 and RM10 have an added column in PlaceTable since those scripts were developed. The Reverse column is another un-normalised element that RM Inc has employed supposedly to expedite display of Place Names in reverse order in response to the “Reverse places” control on the Places pane on the More Options list under the 3-dot vertical ellipsis. That field is updated when a place is added or edited by the RM application but is untouched by my old script which resulted in an empty or null Reverse for the new Places it created. That made the reversed places display virtually useless. I needed a way to update Reverse from the place Name.

Analysis

The Place Names resulting from the conversion are stored in the PlaceTable in a comma-separated string of elements typically containing placedetail (itself could have commas), municipality, county, state/prov, country. However, users are unconstrained by the software and any number and nature of elements might be present, including phrases and complete sentences. There could be any number of commas in a Name string, it could be an empty string or a null or have consecutive commas. What we need in the Reverse column is the same elements in reverse order, e.g., country, state/prov, county, municipality, placedetail (itself could have commas).

Solution

From the RM6 or RM7 era, I had developed PlaceReverse.sql to display Places with up to 3 commas in reverse order. Looking at it now, it seems like a clumsy method and would not scale well. So I returned to AI, giving DeepSeek another shot at developing a query. While it seemed ponderously slow compared to Gemini Flash 2.5 as it typed out its ‘thinking’ at human typing speed, the first iteration worked! With a couple more tweaks, we improved its performance to process the 48,000 records from a few minutes to a few seconds and then constrained it to operate only on user-defined Places, ignoring the built-in LDS Temples and any Place Detail records, to achieve the desired results in 2-3 seconds (your mileage will vary).

(Also compatible with #RM11 )

Count Commas

While working on this big database, I was encountering occasional anomalies in the resulting combinations of PlaceDetail and Place into Place (I’ve since concluded, more or less, that it was my human factor that messed a few things up). But with 48,000 Places, a quarter-million people, RM10 was proving exceedingly slow at scrolling the Place List (and just about everything else). I thought a query that counted commas in the Place Name might catch anomalies of the kind I had seen, e.g., two different Place Names concatenated into one. So I asked DeepSeek to help and, kicking myself that I didn’t think of this method, it produced:

( Should be compatible with all versions from RM4 to #RM11 )

--count commas in Place Name
SELECT
PlaceID,
CASE
WHEN Name IS NULL THEN NULL
ELSE LENGTH(Name) - LENGTH(REPLACE(Name, ',', ''))
END AS comma_count,
Name
FROM PlaceTable
ORDER BY comma_count DESC
;

RM-LineageLoopDetector.sql: Uncovering Lineage Loops in RootsMagic Databases

Breakthrough! Something I’ve wanted for as long as I can remember is a means of detecting lineage loops (an ancestor is their own descendant) in family tree databases created with RootsMagic. This is my second major interaction with Google Gemini Flash 2.5 which took 18 attempts (only 18!) with lots of testing to nail down what I think is amazingly smart code that I could never have conceived and don’t fully understand. It’s robust and highly efficient. Added 2025-08-22: Explanation of script. Updated 2026-07-23: compatible with #RM11 .

Download SQLNote
RM-LineageLoopDetectorOriginal, compatible with RM4-RM11 databases; faster than the next version if its group size covers more than, say, half the population.
RM10-LineageLoopDetectorRequires a RM group named “SQLite Lineage Loop Detector” to contain the people (from 1 to everyone) for whom an ancestral loop is to be sought. Faster than the original when the group is small; better for tackling a very large database. Also returns a “No loop detected” message. Compatible with RM8-RM11 databases. 2025-07-27
Screenshot above and redacted result copied from SQLiteSpy of two loops from a large database.
Child in Problematic Family LinkFull Loop Path (IDs)Problematic Father (Descendant of Child)Problematic Mother (Descendant of Child)Family Where Loop Occurs
John Zzzzz-4278942789->42789N/AN/AJohn Zzzzz-42789=N/A
Duane Michael Xxxxxx-4406644066->44078->44066Anthony Michael Xxxxxx-44078N/AAnthony Michael Xxxxxx-44078=Verna Mildred Yyyyy-44058

Gemini generated the following description, covering what the script does, its design principles, and expected performance:


RM-LineageLoopDetector.sql: Uncovering Lineage Loops in RootsMagic Databases

Genealogical databases, especially those built over many years or compiled from various sources, can sometimes contain logical inconsistencies known as “lineage loops” or “pedigree loops.” These occur when an individual is recorded as being their own ancestor, or an ancestor of their parent, creating an impossible cycle in the family tree. While RootsMagic is designed to prevent some direct entry errors, more complex or indirect loops can slip through.

The RM-LineageLoopDetector.sql script is a powerful SQLite query specifically designed to identify and report these problematic lineage loops within your RootsMagic database.

What it Does

This script scans your RootsMagic database to find instances where:

  • A person is recorded as their own parent/ancestor (self-loop).
  • A person’s parent is also a descendant of that person (a more complex cycle).

For each loop detected, the script provides clear, actionable information:

  • Child in Problematic Family Link: The individual whose family relationship initiates the discovered loop.
  • Problematic Father / Mother (Descendant of Child): Identifies which parent in the problematic family is also a descendant of the child.
  • Family Where Loop Occurs: Provides a user-friendly representation of the family (e.g., “Father’s Name-ID=Mother’s Name-ID”) that contains the specific link causing the loop. This is crucial for RootsMagic users, as FamilyIDs are not visible in the application’s interface.
  • Full Loop Path (IDs): A sequence of PersonIDs illustrating the exact path taken to complete the loop, making it easy to trace the issue within RootsMagic.

The script is carefully designed to report only one canonical instance for each unique lineage loop, avoiding redundant results even if multiple paths within the loop could technically trigger detection.

How it Was Designed

The development of this script involved an iterative process to balance accuracy, performance, and user-friendliness:

  1. Recursive Common Table Expressions (CTEs): The core of the solution leverages SQLite’s WITH RECURSIVE functionality. A CTE named CycleFinder performs a depth-first search through the family tree’s parent-child relationships.
  2. Targeted Loop Detection: Instead of building a complete ancestor list for every person (which is inefficient for large databases), CycleFinder starts its search from every direct child-parent link in your database. It then attempts to trace ancestors from the parent’s side, looking for the original “child” that initiated that specific path.
  3. Efficient Cycle Prevention: Early iterations struggled with performance due to string manipulation (INSTR function) within the recursive path tracking. The current design judiciously uses INSTR to prevent infinite recursion and detect general path revisiting, but the primary loop detection is based on the current_person_id eventually equalling the start_person_id (the child who began the trace). This balance significantly improved performance.
  4. Canonical Loop Reporting: A RankedLoops CTE was introduced to address the challenge of reporting a single, meaningful instance for each unique loop. This CTE uses a sophisticated PARTITION BY clause that extracts all unique PersonIDs involved in a detected loop, sorts them, and concatenates them into a consistent “canonical loop identifier.” ROW_NUMBER() then selects the shortest or lowest-FamilyID loop from that canonical set, ensuring clean, non-redundant output.
  5. User-Centric Output: Recognizing that RootsMagic users don’t see FamilyIDs, the final SELECT statement includes intelligent joins to the NameTable to convert FamilyIDs into human-readable “FatherName-ID=MotherName-ID” format, directly assisting users in locating and correcting errors within the RootsMagic application.

What Performance to Expect

The script is optimized for performance within the constraints of SQLite’s recursive CTE capabilities:

  • Small to Medium Databases: For databases up to tens of thousands of records, you can expect the script to execute very quickly, often in a matter of milliseconds to a few seconds.
  • Large Databases: For very large databases (e.g., hundreds of thousands of Child and Family records), the execution time will naturally increase. Recent tests on a database with 274,000 ChildTable records and 159,000 FamilyTable records completed in approximately 3 minutes 45 seconds on a 7-year-old Intel i5 processor. While this isn’t instantaneous, it is a very reasonable time for performing a comprehensive graph cycle detection on such a scale.
  • Factors Affecting Performance: Your computer’s processing speed (CPU, RAM, SSD vs. HDD) and the depth/complexity of your family tree (very long, unbroken lineages will require deeper recursion) will influence actual execution times.

In summary, the RM-LineageLoopDetector.sql script provides an efficient and user-friendly way to maintain the integrity of your RootsMagic family history data by accurately pinpointing and describing otherwise hidden lineage loops.


If you’ve read this far and want more detail on the development process, you should view the dialog I had with Gemini at https://g.co/gemini/share/2cdd5db67e6f.

Unlocking Your RootsMagic 10 Data: A Deep Dive into SQLite Queries (with AI)

I just finished a session with the free Google Gemini Flash 2.5 model to develop a quite complex query to identify couples in a RootsMagic database who are cousins of each other (see the discussion that led to it in the Forum at https://sqlitetoolsforrootsmagic.com/forum/topic/cousin-marriages/). That was preceded a few months back by a session with DeepSeek trying to develop a query that could act as an alternative to RM’s Set Relationships tool – it was not as successful but it might be more so now as its model evolves and grows. Anyway, that caused me to ask Gemini some questions about how to effectively use it to develop SQLite3 queries for RootsMagic databases. That “conversation” can be read in full at https://g.co/gemini/share/b9ef037e35c6 but I asked it to generate a summary for this post, pasted below.


Unlocking Your RootsMagic 10 Data: A Deep Dive into SQLite Queries

RootsMagic 10, like its recent predecessors, stores all your precious genealogical data in a robust SQLite database file (typically with a .rmtree extension). This self-contained, file-based relational database is embedded directly within the RootsMagic software, making it incredibly efficient for personal use.

While RootsMagic’s interface is fantastic for managing your family tree, sometimes you need to dig deeper – to run custom reports, analyze specific data patterns, or extract information in ways the software doesn’t natively offer. This is where direct SQLite querying comes in.

Key takeaways for RootsMagic users:

  1. SQLite is Your Data’s Foundation: Your entire family tree, including persons, events, sources, citations, and media, resides within a structured SQLite database.
  2. Access with Caution (and Backups!): You can explore your .rmtree file using third-party SQLite tools (like DB Browser for SQLite or SQLiteSpy). Always create a full backup of your database before attempting any direct access or modification!
  3. Understanding the Schema is Key: To write effective queries, you need to know the specific table names (e.g., PersonTable, EventTable, SourceTable) and column names (e.g., FirstName, LastName, Date1, Title) within the RootsMagic schema. These are the “building blocks” of your queries.
  4. How AI Can Help (with your input): AI models like Gemini can assist in generating complex SQLite queries. However, because they don’t have real-time access to your specific database’s schema, you’ll need to provide the relevant table and column names to ensure the queries are accurate.
  5. Leverage Context in Conversations: If you’re working with an AI, you can generally continue to refine and develop multiple queries within the same chat session, as the AI will retain context of the schema details you’ve already provided. For new chat sessions, a quick reminder of the core table/column names will be helpful.

By understanding the SQLite foundation of RootsMagic and learning how to craft (or have an AI craft!) custom queries, you gain unparalleled power to analyze and utilize your genealogical data in new and exciting ways. Just remember the golden rule: Always back up your database before you begin!


That summary of the responses to my prompts up to that point of the session really missed a lot of what Gemini said so it’s worth delving into the conversation for more insight into points 4 & 5 and how an AI might become repetitive or forget or veer off due to an error in input or interpretation, as happened in my session with DeepSeek and even to a degree with Gemini that I was able to catch and correct.

I went on in the conversation with Gemini to discover that content lifted from the RM10 Data Dictionary in CSV format and pasted into the Chat could provide it with important parts of the database schema that it readily understood. Until now, I have been typing in the bare minimum description to provide the context with which the AI engine is to work. If a comprehensive description of the schema can be easily provided to the AI engine, that will make development of custom queries much easier. At the moment, the prompt capacity is not large enough to accept the entire sheet named “RM10 Data Def Project” as CSV text.

The raison d’etre of this website is to “Exploit your RootsMagic family tree database with SQLite Tools”. AI assistance in creating new and more powerful “SQLite Tools” looks to be within reach at no or low $cost for those with a good understanding of the RootsMagic database design and SQL.

New Page for Tool Requests

Stemming from recent discussion in the RootsMagic Community about the desire for a system to track Feature Requests for the RootsMagic application, I was curious to see what might be readily available and came across a free plugin for WordPress: Simple Feature Requests Free – User Feedback Board By Patrick Garman. I’m not offering to host one for RM but I thought it might be useful to add it to this site to handle the occasional request for a SQLite-based tool for interaction with a RM database. You’re welcome to float a trial balloon to see how the plugin works and then delete your request if it’s nothing more than that. You can access the page via the top menu bar or directly at: Tool Requests.

Custom functions in SQLiteSpy with sqlean extension are mighty and fast!

Intro

I first reported on the #sqlean extensions for SQLite3 in my 2022 post In Praise of SQLite. What I did not pick up then that I have just now discovered is that sqlean supports the creation of user-defined or custom functions using SQLite syntax. Maybe it did not at that time or my fluency in the language of code development is just too poor to have recognised it. Regardless, I have now been enthusiastically exploring that capability, hitting lots of bumps but thrilled that, at last, I’ve found a way to take complex SQL and package it into a function that greatly simplifies and eases the development of scripts that interact with the RootsMagic database structure. And there is an acceptable penalty in performance that only becomes noticeable on large datasets or slow systems.  

Moreover, a custom function can be easily created in #SQLiteSpy by copying a block of SQLite code from a working script into Notepad++ for minor changes and, thence, into the SQLiteSpy editor. To illustrate, I will focus on the conversion of the script in the post Date Decoder to the function rmDateDecode().

Performance

Custom functions may seem a simple matter for those with skills in a language that can interact with SQLite. For those of us closer to the luddite end of the spectrum, they seem out of reach. Some years ago when I saw that SQLite Studio supported custom SQLite functions, I dove in only to be greatly disappointed by its performance; that was a dead end. So I was delighted that there was no obvious penalty in moving a complex string parsing and conditional string building code from a script into a sqlean custom function, as reported in the table below.    

rmDateDecode() tested on the same database having 8368 rows in the EventTable, 3940 of which had a text or valid date:

Regular SQL Script in
SQLiteSpy 3.47.2 
SQL function in
SQLite Studio 3.4.13 
sqlean SQL function in
SQLiteSpy 3.47.2
~40ms~44000ms~60ms

Installing the extension

This message in the SQLiteSpy extensions dialog gave me pause (and still makes me a little unsure): 

While I have experienced many bumps building the rmDateDecode() function, I have tested many of the functions included in sqlean and they all work. And, once working, my custom function has been reliable.

Download Windows 64-bit package and extract either define.dll (and other extensions, if desired) or the bundle of extensions included in sqlean.dll to the same folder as your executable for SQLiteSpy.exe Win64-bit edition.

The SQLiteSpy extensions dialog is accessed via the menu Options > Options > Extensions.

Type in the name of the extension file and, if not in the same folder, the relative or full path. Mine is in a sub-folder named ‘sqlean’. The extension will load the next time SQLiteSpy opens or connects to a database. It manifests itself as an empty table named ‘sqlean_define’ when there is no connected database.

With the extension successfully loaded, you’re ready to begin using functions built into sqlean. Try some examples from the Main Set. For the rest of this post, our attention will be on the define set.

Building a custom function per the instructions

I was puzzled at the outset that the examples for scalar functions did not seem relevant to what I wanted for decoding values from the Date column of RM’s EventTable. However, with a test RM database connected, I blundered ahead at making a simple function that would extract the first yyyymmdd string from [Date].

SELECT define(‘rmDateExtract’, ‘SUBSTR(:rmDate, 4, 8)’);

Executing that statement added the following record to the sqlean_define table:

nametypebody
rmDateExtractscalarSUBSTR(:rmDate,4 ,8)

…and did whatever is necessary in memory to make the function accessible to the SQLite engine.

‘:rmDate’ is what I chose as the name of the one variable to be passed to the function. Then the SQLite statement:

 SELECT rmDateExtract([Date]) FROM EventTable;

…sends the value of the Date field from each row in the table to the function which returns the substring.

rmDateExtract(Date)
19200101
19180307
19920215

That’s certainly more readable than what is stored:

DatermDateExtract(Date)
D.+19200101..+00000000..19200101

…but we want to do better. And here’s where the fun and frustration began.

Note that the define() syntax requires the SQL code to be a string within single quotes. However, the DateDecoder.sql script has string values to compare, to be concatenated, or empty strings to be issued. I ran into this issue using a Visual Studio C# years ago to build my old #rmtrix utility. Conversion of working, regular code of this sort into a string that would be correctly presented to the SQLite engine was a trial and error headache. A regular line like this:

Coalesce( Nullif( '-' || Substr( [Date] , 10 , 2 ) , '-00' ) , '' )

has to be converted to this:

Coalesce( Nullif( '||'''-'''||' || Substr( :rmDate , 10 , 2 ) , '||'''-00'''||' ) , '''' ) 

I got it almost right using Notepad++ the first time but “almost” is a fail. Ultimately, after many fails, I narrowed it down to the empty string '' (2 single quotes). While '''-''' is needed to pass '-' to SQLite, '''''' does not pass on ''; the sequence '''' does! (those are all single quotes)

An easier, more reliable way to build a custom function

Here was the Eureka! Moment. What ended up in the sqlite_define.[body] cell was the original regular code. Moreover, that is a permanent table unless explicitly DROPped from the database. And whatever sqlean put into memory for a custom function is gone once SQLiteSpy is closed, maybe even when the database is disconnected. That implies that sqlean reads the table on opening or when a custom function is called and does its magic in memory. So what if I inserted an empty record into the table and edited it with SQLiteSpy directly to add a function? I copied the block of regular SQL into the [body] cell and filled the other two cells appropriately. Closed and reopened SQLiteSpy on the database and tried the function. Voila!

This is so much easier and is what one can do in the SQLiteStudio interface; it’s a pity that it is such a slug. Here’s a shot of the sqlite_define table contents with three user-defined functions:

A Caution

One thing I am experiencing which remains concerning is that on closing a connection or the app, I frequently, if not always, get the following error message since diving deep into custom functions with sqlean: 

I also get a “database is locked” message at times when adding or editing a function in the sqlean_table. The two may be related but I do not know the cause. Hopefully, this is not a sign of possible corruption per the warning from the SQLiteSpy Extensions dialog window.

And there are sqlean instructions about memory:

define_free()
Frees up occupied resources (compiled statements cache). Should always be called before disconnecting. E.g. select define_free();

I don’t know whether closing SQliteSpy releases the cache. If not, we’ll have to see if there is an erosion of available memory over time.

Download

This is the block of SQL for pasting into the [body] cell for the rmDateDecode scalar function in the sqlean_define table.
